For web and app services on Linux or Windows servers.
Once your team approves a fix, no one on call types it.
AI drafts the fix. Your engineer corrects it. Your team approves it once, for every server. When an alert fires, at any hour, Virca runs it with no one at a terminal.
Virca is AgenticOps for IT infrastructure.

AgenticOps
What AgenticOps is. How Virca is one.
AgenticOps is AI agents in IT operations that investigate, act and confirm the result, while people make the decisions.
Your engineer sets the scope. AI works within it. Your team approves it. The Worker runs it.
The Virca Worker is a process on your server. It watches the server and runs the fixes you approve. Every run leaves a record.

One night on call
The same fault, fixed by hand on server after server.
The alert at 2:30 AM is usually one your team has seen before. Tonight it is web-03: nginx is running, but /healthz times out. The service waits until someone logs in.
Tonight nginx didn’t exit, so Restart= did not fire. It also doesn’t check that the service answers, or tell your team.

How · writing the fix
Your engineer and AI write the fix down. Your team approves it.
An ActionBook is a fix written down as one file your team can read and approve. AI drafts it from the live server. Your engineer corrects it. Neither half works alone.
This ActionBook runs only after your team approves it.

- 1AI
AI reads web-03
- 2AI
AI drafts the ActionBook
- 3Your engineer
Your engineer corrects it
- 4Your team
Your team approves it
How · what runs, and when
Your team draws the line. Virca works inside it.
When an alert fires, Virca checks it on the server. If an approved fix fits, Virca runs it and re-checks its target. If nothing fits, it stops and tells your team.
An alert can’t start a fix until your team turns on the fix for that alert.
With approval mode on, every run an alert starts waits for approval in Virca.
Not every event ends in an action, and that is the point. If the problem has already cleared, Virca stops there, and no one is called.
If a step fails, the reverse steps its author wrote run in reverse order. If there are none, recovery is manual, and the record says so.

What changes
What your team gets back.
Your on-call engineer’s hours
Their hours can go to the alerts that need a person. Virca runs the fix your team already approved.
One fix, written down
Your team reads and approves each fix as one file. The Worker runs that same version on every server you assign.
A record to read
Every run shows what ran, where, and who or what started it. Your team can read it the next morning.
Your service, back at any hour
When the alert fires at 2:30 AM, Virca runs the approved checks on web‑03, then the fix, and re-checks that /healthz answers.
Alongside what you run
Nothing to remove. Nothing to connect.
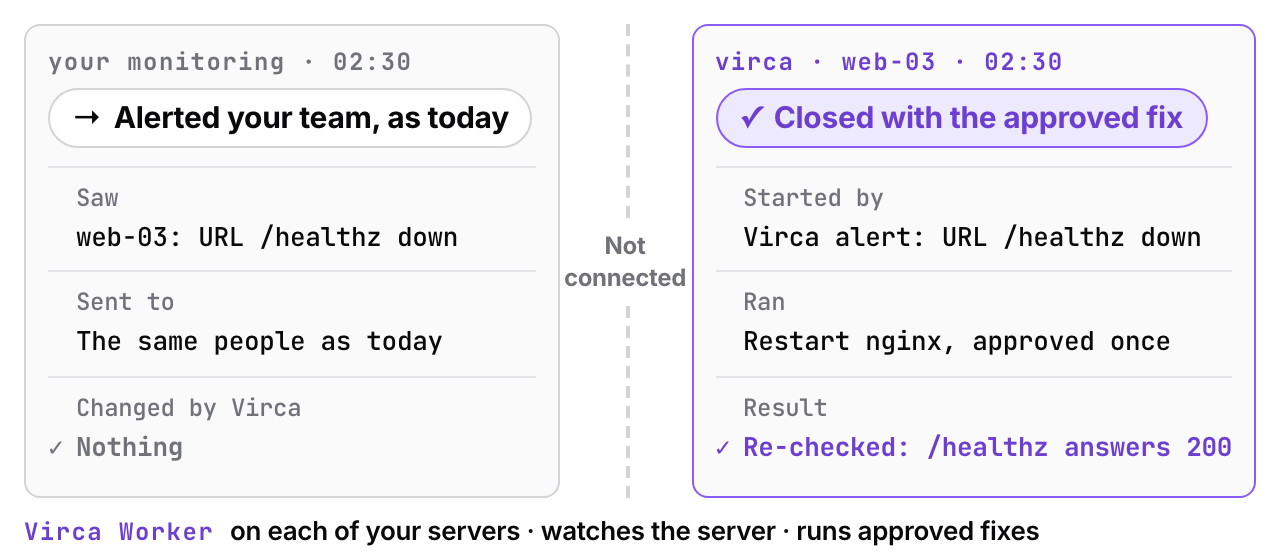
Monitoring is built in. Virca runs alongside what you already have, and doesn't depend on it.
At 2:30 AM, your monitoring may see web‑03 too. Your current alerts still reach the same people as today. The record shows whether the fix already ran.
Budget
Before you ask for budget.
Forward this page to whoever signs off.
Your service does not wait for someone to log in. Your team approves what runs, and where. Change review can read that approved set before anything runs, and the record after.
The cost today
A repeat outage lasts until someone logs in and types the fix.
To size it, count last quarter’s outages that ended in a fix your team had typed before.
Count your downtime cost →Who builds it
Built by Whatap Global Inc.
The US subsidiary of WhaTap Labs, a monitoring company.
About WhaTap Labs →The security review
A fix can only call functions already on the Worker. It runs only on the servers you assigned.
Email your questions to ask@virca.ai with the subject “Security review.”
What runs, and who approves →The price
$20 per server per month.
A server is any machine you install the Worker on.
Next step
Start on one non‑critical app server.
Read-only checks first, then one fix.
- 1Install the WorkerInstalled with sudo. Runs as root by default, or as another user you choose. Some functions may need root. One outbound connection.
- 2Let Virca look firstConnect email or Slack. Let Virca look into the alerts on that server. Those checks are read-only. Read the runs.
- 3Turn on one fixThen your team approves one fix, such as restarting nginx, and turns it on for its alert. Later, assign it to more servers.
Before you start
We have systemd and cron. Why add Virca?
Keep them. On its own, systemd brings back a process that exits. It doesn’t check that the service answers or tell your team. A cron cleanup runs on a schedule, and the disk can fill between runs. The Worker runs an ActionBook your team approved. It checks that the alert is real, acts, re-checks its target and reports each step.
How much work is the setup, honestly?
General patterns, such as a filling disk or a stopped service, need very little input. Patterns specific to your stack need an engineer for a first pass. The work happens once per pattern, not once per incident.
Why not my AI agent?
Keep it. With Virca, your team approves the fix once, before the alert. Then it runs on the servers you assigned, at any hour. With approval mode on, every run an alert starts waits for approval in Virca. Every run is on the record. If no approved fix fits, Virca stops and tells your team.
What can it run on my servers, and who decides?
A fix can only call functions already on the Worker. It runs only on the servers you assigned. An alert can’t start a fix until your team turns on the fix for that alert.