How it works
From the alert to the record: what each run does.
Your team approves a fix and turns it on for its alert. When that alert fires, the Worker on that server runs it in four steps. Each step goes on the record.
The Virca Worker is a process on your server. It watches the server and runs the fixes your team approves.


How a fix is written
Your engineer and AI write the fix down.
AI drafts from the live server. Your engineer corrects it. Neither half works alone. The fix becomes an ActionBook: one file your team can read.
This ActionBook runs only after your team approves it.


- 1AI
AI reads web-01
nginx stopped
- 2AI
AI drafts the ActionBook
VALIDATE · INVESTIGATE · ACT (restart nginx) · CONFIRM
- 3Your engineer
Your engineer corrects it
nginx only. Other services stay as they are.
- 4Your team
Your team approves it
Linked to an alert rule, for the servers your team assigns.
- 1AI
AI reads web-03
/healthz times out · nginx running, not answering
- 2AI
AI drafts the ActionBook
VALIDATE · INVESTIGATE · ACT (restart nginx) · CONFIRM (/healthz 200)
- 3Your engineer
Your engineer corrects it
nginx only. Other services stay as they are.
- 4Your team
Your team approves it
Linked to an alert rule, for the servers your team assigns.
- 1AI
AI reads web-06
disk 78% · /var/log/app 38 GB · files older than 7 days
- 2AI
AI drafts the ActionBook
VALIDATE · INVESTIGATE · ACT (delete logs older than 7 days) · CONFIRM
- 3Your engineer
Your engineer corrects it
Audit logs stay.
- 4Your team
Your team approves it
Started by your team, for the servers your team assigns.
One run
What happens when an alert fires?
When an alert has an approved fix, the Worker runs it one step at a time.
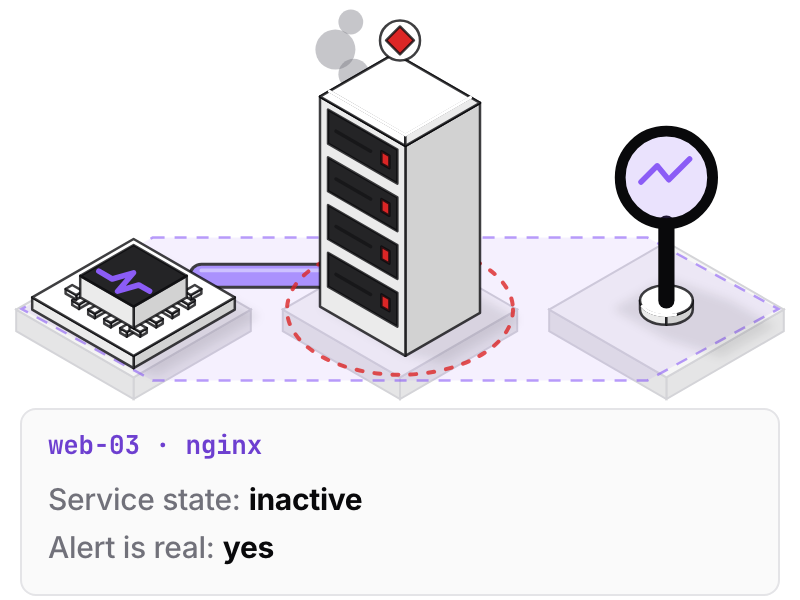
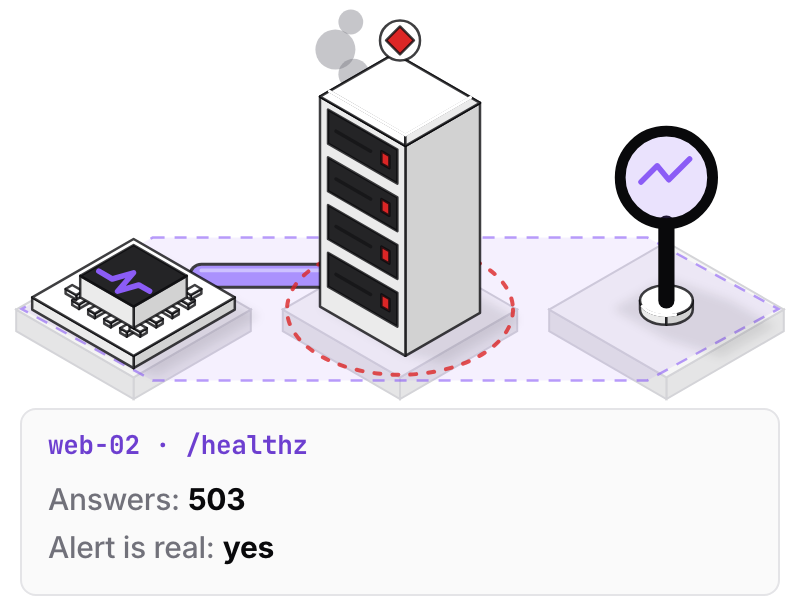
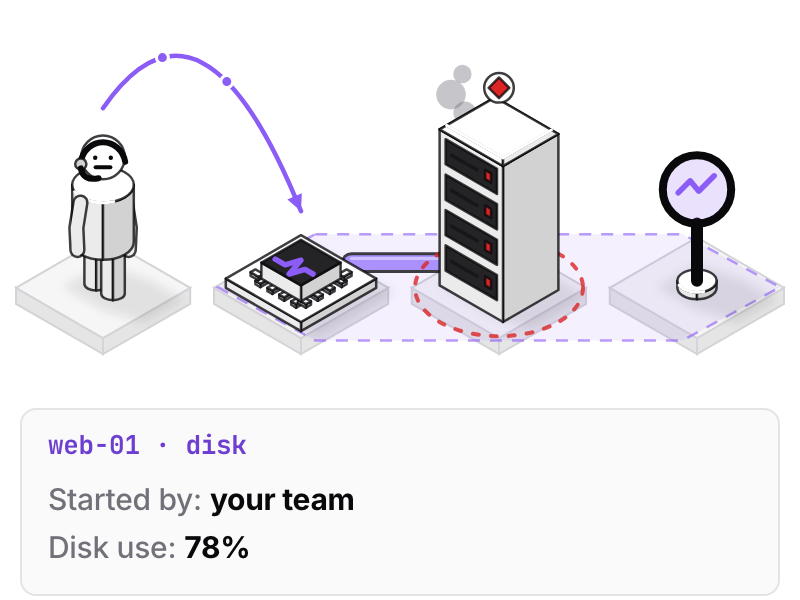
01 · Validate
The Worker checks that the alert is real.
If the problem is already gone, the run ends here, and no one is called.
More on Validate →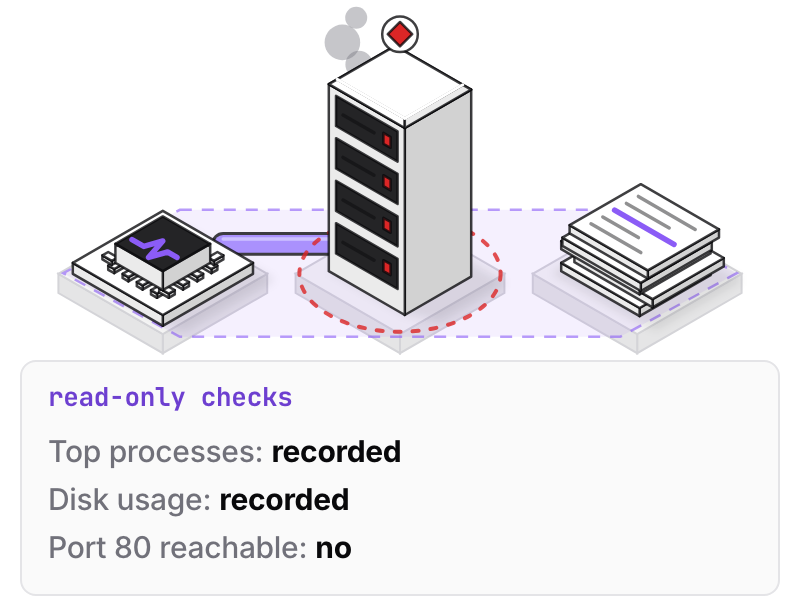
02 · Investigate
The Worker gathers what the alert didn't say.
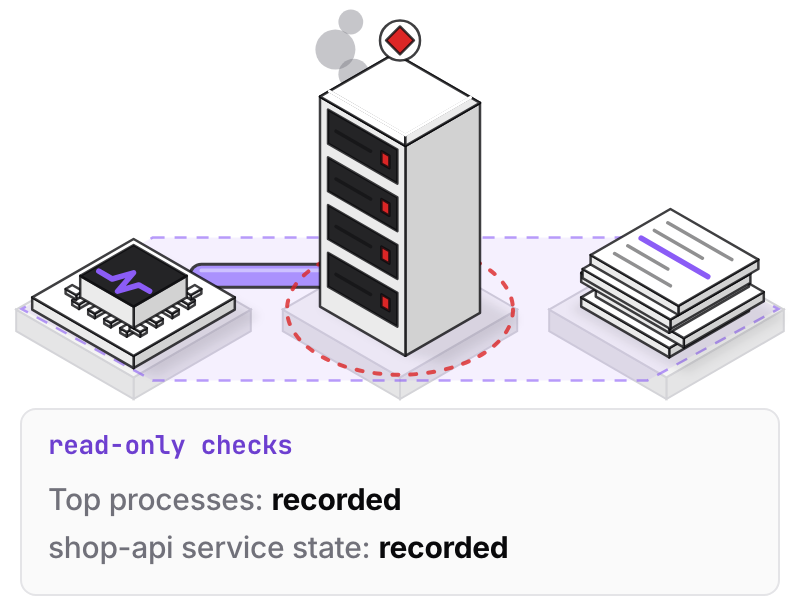
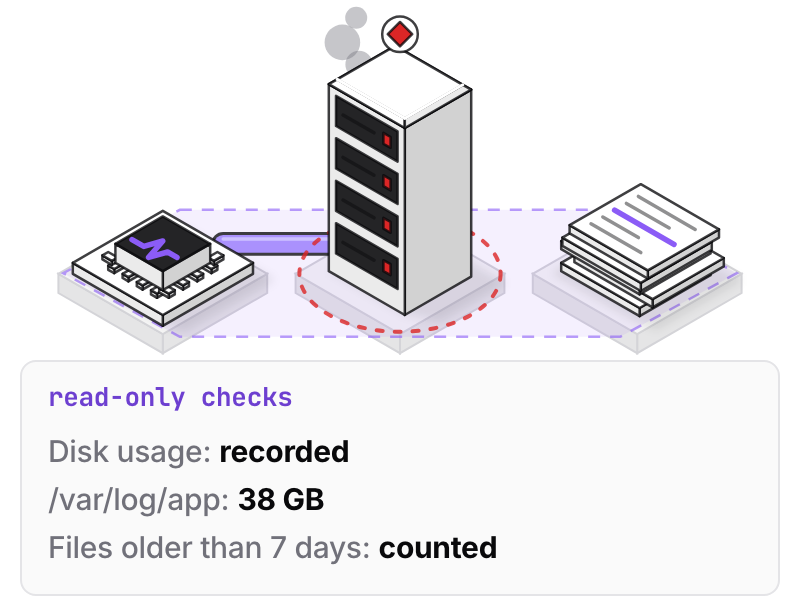
Read-only checks record processes, disk and ports before the fix runs.
More on Investigate →
03 · Act
The Worker runs the fix your team approved.
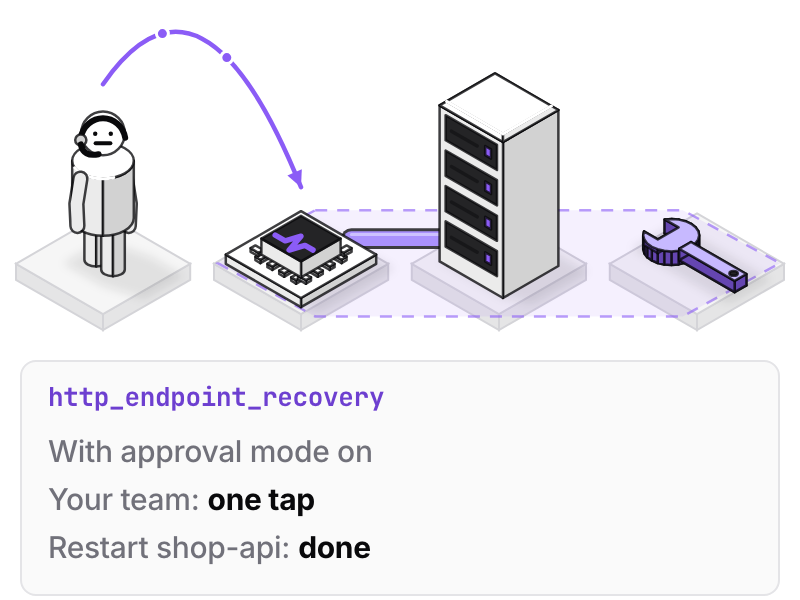
With approval mode on, every run an alert starts waits for approval in Virca. A fix can only call functions already on the Worker.
More on Act →
04 · Confirm
The Worker re-checks the target.
If a step fails, its reverse steps run. If there are none, recovery is manual, and the record says so.
More on Confirm →
No known fix
The Worker looks into the server first.
When a port stops answering and no fix is set for it, the Worker runs read-only checks and records what the server shows. Your team takes over from there.
Virca records what the Worker saw, without claiming a cause.

If a fix fails
The run is marked failed.
If a step fails, the reverse steps its author wrote run in reverse order. If there are none, recovery is manual, and the record says so. Your team hears about the run through the alert notification your team set up.

The record
See what the Worker did.
Every run is recorded step by step: who or what triggered the run, what ran, on which server, and what happened after.
Your team approves the fix before and reads the record after.

Getting started
Start on one non‑critical app server.
Set up once for each pattern. Common patterns need very little input. Incidents specific to your stack need an engineer for a first pass.
- Install the Worker Installed with sudo. Runs as root by default, or as another user you choose. Some functions may need root. One outbound connection, no inbound port. $20 per server per month.
- Let Virca look first Connect email or Slack. Let Virca look into the alerts on that server. Those checks are read-only. Read the runs.
- Turn on one fix Then your team approves one fix and turns it on for its alert. Later, assign it to more servers.

